Full-Stack AI Infrastructure

GPU Cloud, Dedicated Clusters & Infrastructure Deployment and Operations Support

From single GPU instances to large-scale bare-metal clusters — three service tiers to meet every AI infrastructure need. Available configurations and terms are provided on request.

Full-Stack AI Infrastructure

What do you want to achieve?

Select the goal that best matches your situation to review the relevant service features and considerations. Specific configurations and scope are worked out through consultation.

Start small-scale AI development or testing

For those exploring GPU environments suited to their timeline and usage needs.

Public Cloud GPU

Build a dedicated AI compute environment

For those considering a private environment tailored to their processing scale and data requirements.

Private AI Cluster

Outsource AI infrastructure build and operations

For those looking to reduce the burden of setup, monitoring, and maintenance through managed support.

Managed AI Factory

Coming Soon

Embed AI inference into business workflows or products

For those exploring inference services to power AI-generated responses and document processing.

Token Factory

Want to compare your options side by side?

Compare the three services

Service Delivery Flow

01

Discovery

We carefully assess your AI workloads, requirements, and budget.

02

Proposal & Design

We design the optimal service tier and infrastructure configuration with a detailed proposal.

03

Deployment

After approval, our specialist team deploys and builds quickly and reliably.

04

Operations & Improvement

We continuously monitor and improve your AI infrastructure after go-live.

Public Cloud
01 / Public Cloud

Public Cloud

Developer-friendly on-demand compute. Launch Jupyter Notebook and ML environments quickly with a flexible pay-as-you-go model — from small-scale experiments to full production workloads.

  • Fast Environment Launch — Spin up Jupyter Notebook and ML environments quickly. Start developing immediately.
  • Pay-as-You-Go — Flexible pricing — pay only for what you use. Start with low upfront cost.
  • Wide GPU Lineup — Latest GPUs including NVIDIA H100, A100, and L40S available from a single instance.
  • Developer Friendly — Manage resources via REST API, CLI, and web console. Integrates into DevOps workflows.
Discuss Public Cloud
Private AI Cluster

800G

InfiniBand

5,000

Max GPU

Dedicated

Bare-Metal

* 800G InfiniBand and up to 5,000 GPUs delivered via partner infrastructure. Configuration and terms provided on request.

02 / Private AI Cluster

Private AI Cluster

Bare-metal clusters for Tier-1 clients. High-speed network fabric enables large-scale GPU cluster configurations in a fully dedicated environment. Available configurations and terms are provided on request.

High-Speed Network Fabric

Ultra-low latency, high-bandwidth network optimizes communication between GPU nodes.

Large-Scale GPU Cluster

We propose GPU cluster configurations suited to large-scale LLM training and simulation workloads.

Dedicated Bare-Metal

Fully dedicated environment with no shared resources. Ensures security and stability.

Custom Configuration

Customize network topology, storage, and cooling systems to your exact requirements.

Discuss Private Cluster
Managed AI Factory

Infrastructure Overview

High-Speed

Network

InfiniBand-capable

Large-Scale

GPU Scale

Bare-Metal

Fast

Launch Time

Cloud Env.

High

Availability

Terms on request

03 / Managed AI Factory

Managed AI Factory

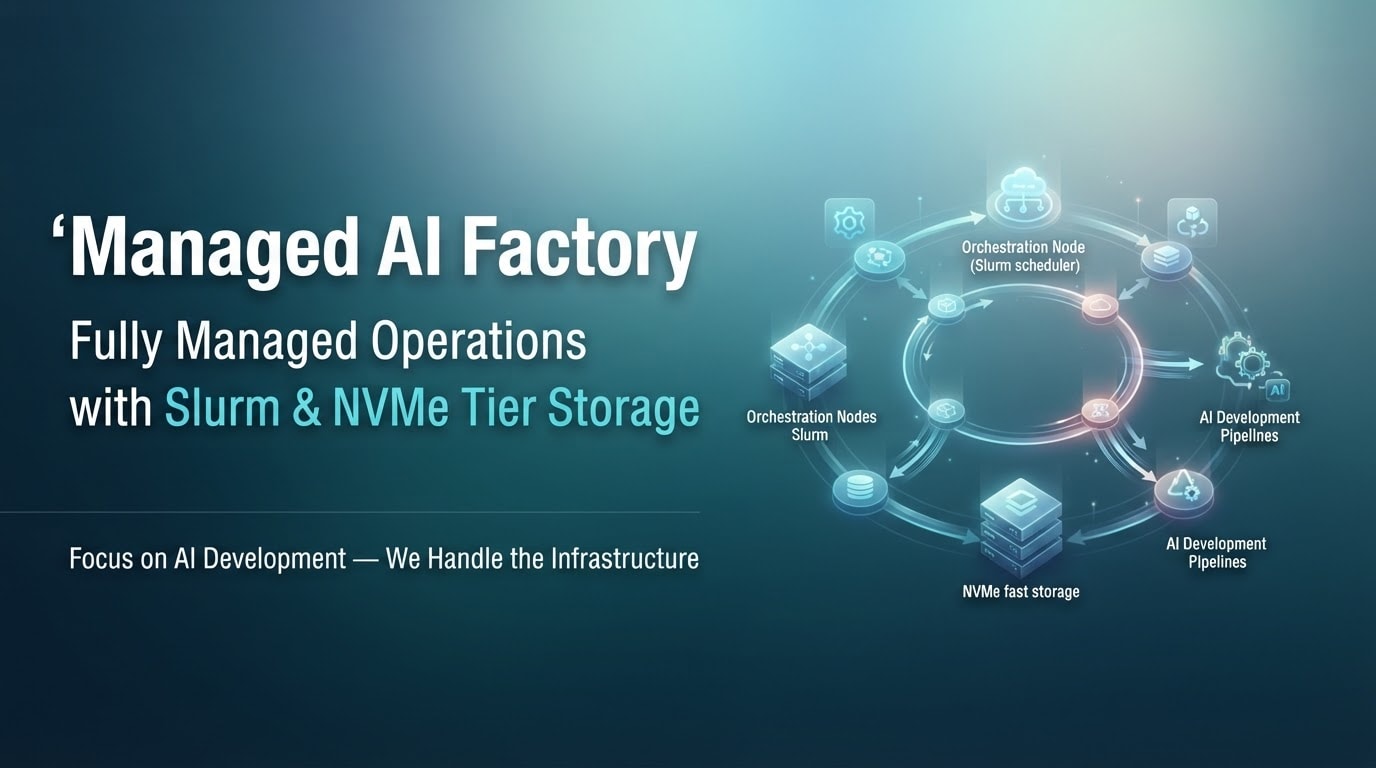
Fully managed operations service. bloomax builds and operates the environment — including high-speed networking, NVMe tiered storage, and Slurm orchestration — so you can focus entirely on AI workloads.

  • Slurm Orchestration — Industry-standard Slurm job scheduler efficiently manages large-scale HPC workloads.
  • NVMe Tiered Storage — Tiered storage combining high-speed NVMe SSDs and high-capacity HDDs optimizes I/O performance.
  • High-Speed Network — High-bandwidth network optimizes inter-node communication and improves training efficiency.
  • Fully Managed Operations — We handle all monitoring, incident response, and maintenance — you focus on AI development.
Discuss Managed AI Factory
Service Comparison

Compare the Three Service Tiers

Public Cloud GPU

Intended Use

Development, validation, small-scale start

Environment Type

On-demand (pay-as-you-go)

Build & Operations Responsibility

Customer manages independently

Key Items to Confirm at Consultation

GPU type, usage volume, duration

Private AI Cluster

Intended Use

Large-scale LLM training and inference

Environment Type

Dedicated (bare-metal)

Build & Operations Responsibility

bloomax supports build (operations model discussed at consultation)

Key Items to Confirm at Consultation

GPU count, network requirements, security requirements

Managed AI Factory

Intended Use

Sustained AI workload operations

Environment Type

Fully managed (details on request)

Build & Operations Responsibility

bloomax handles both build and operations

Key Items to Confirm at Consultation

Workload details, SLA requirements, operations structure

Configurations, pricing, and scope for each service are provided on request. This comparison is based on currently published information.

CONSULTATION EXAMPLES

We welcome inquiries at any stage.

Not sure which GPU you need. Considering a dedicated environment. Want to know how much of the build and operations you can hand off. bloomax helps you clarify your requirements and find the right AI infrastructure approach for your use case. Reach out even before your specifications are finalized.

The examples below are illustrative scenarios, not actual case studies. Scope and terms are confirmed individually.

01

We want to use GPUs for AI development and testing

Challenge

We want to start validating AI models but are unsure which GPU to choose or how much compute we need. We'd like to explore cloud options before committing to hardware purchases.

Related service:Public Cloud GPU

What we clarify together

  • Model type and workload (training, inference, etc.)
  • Estimated data volume and GPU memory requirements
  • Number of users, testing period, and budget
  • Existing development environment and data handling requirements

Configuration and approach

We explore public cloud GPU options suited to your validation needs. After clarifying what you want to test and which conditions to evaluate, we present available GPU options and terms.

02

We want a dedicated AI compute environment

Challenge

As AI usage grows, we're considering a dedicated GPU cluster. We want to think through not just performance, but also integration with existing systems, data handling, and operational structure.

Related service:Private AI Cluster

What we clarify together

  • AI workloads and expected processing volume
  • Required GPU configuration and future scaling plans
  • Network and storage requirements
  • Data location, access control, and integration with existing systems
  • Timeline, budget, and internal operations capacity

Configuration and approach

We explore dedicated GPU cluster options covering compute, network, and storage. We clarify the responsibilities of your team, bloomax, and any technology partners involved, then confirm the conditions for deployment.

03

We want to reduce the burden of building and operating AI infrastructure

Challenge

We want to advance AI development, but handling infrastructure build, monitoring, and maintenance in-house is difficult. We'd like to clarify what to manage internally and what to delegate, and establish a sustainable operations model.

Related service:Managed AI Factory

What we clarify together

  • Current equipment and system configuration
  • Internal staff and scope of manageable tasks
  • Requirements for monitoring, maintenance, and incident response
  • Approach to updates and configuration changes
  • Operations budget and required support scope

Configuration and approach

We explore Managed AI Factory options covering the scope of build and operations support. Including whether existing equipment can be utilized, we define the tasks, responsibilities, communication structure, and contract terms on a case-by-case basis.

FAQ

Questions Before You Reach Out

Here are common questions about configuration, costs, and post-deployment operations. You are welcome to get in touch even before your requirements are fully defined.

Reach out even before your requirements are set.

We support your planning process from the moment you share your use case or challenge.

Talk to us about AI infrastructure